This translation is not available yet. Showing the original article.
When posts on social media are all generated by AI, why should we still spend time reading them?
Someone can generate a post in seconds, yet we spend minutes reading it.
If the goal is to improve our knowledge, why not just ask the model directly instead of reading someone else's post?
Could it be that, when we read, what we are really consuming is someone else's interests and preferences, or what they want us to see, and that the content itself has little value—that we are looking at the person rather than the words?
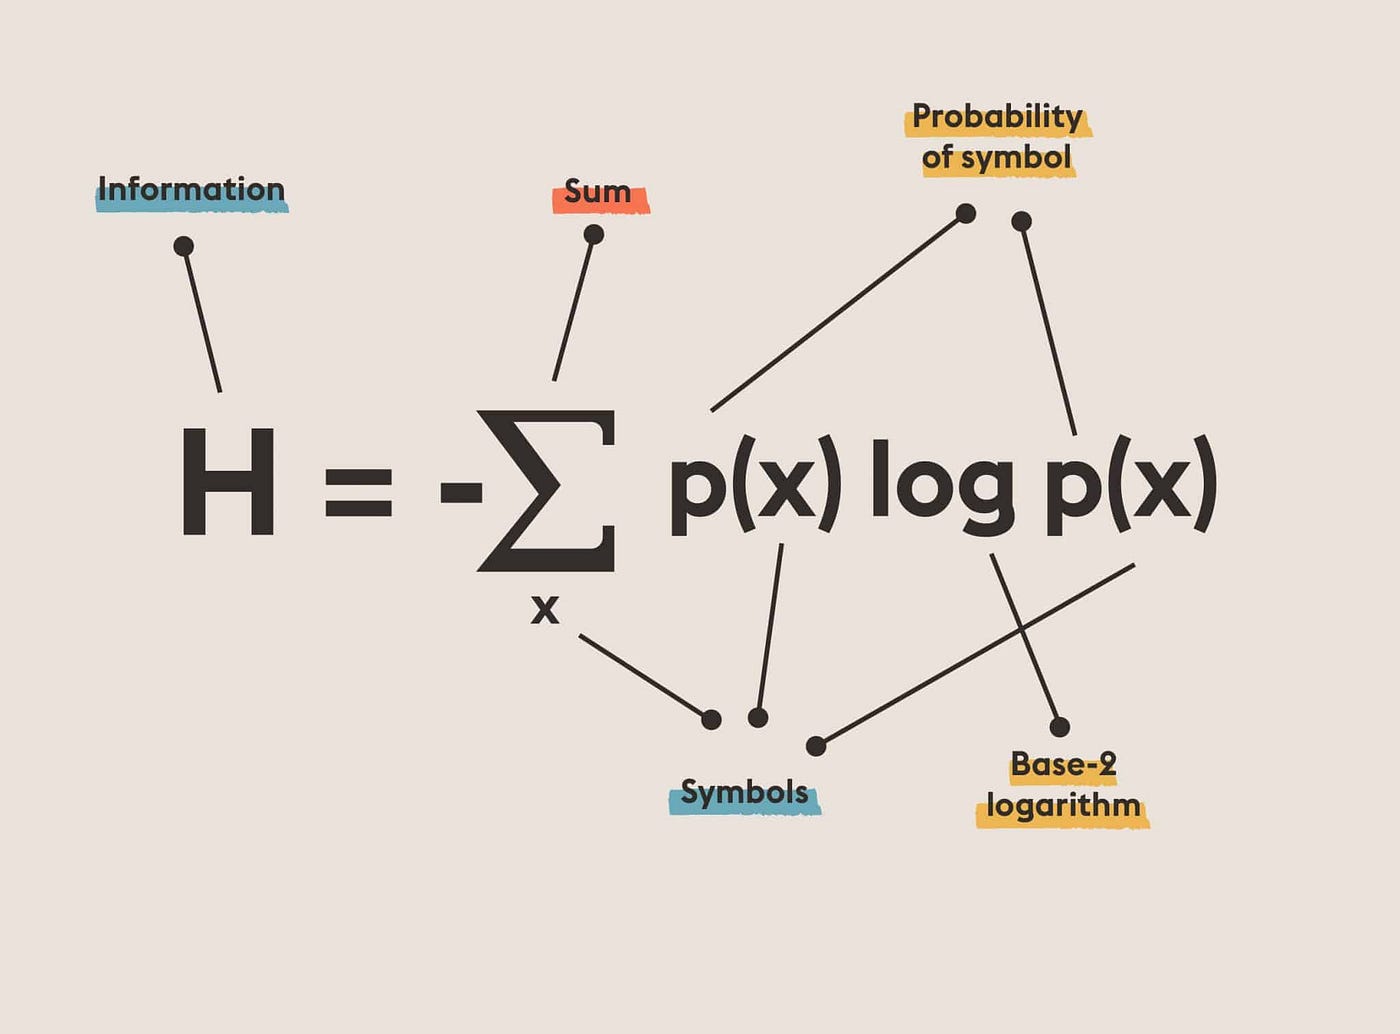
From the perspective of information theory, what does this mean? How would Shannon see it?
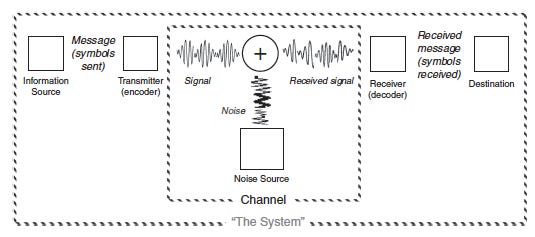
In the past, we primarily transmitted information through text. But with the development of the modern internet, much content can be replaced with abbreviations—like "NBA"—because human knowledge bases and the internet can automatically decode them.
So, what happens when we
have large language models?
If we can generate a full article with a single prompt, is the real information contained only in that prompt?
Is what truly needs to be transmitted simply the prompt and the model settings behind it?
After all, a 2000-word article might just be an expansion of a 30-word prompt.
When posts on social media are all generated by AI, why should we still spend time reading them?
Someone can generate a post in seconds, yet we spend minutes reading it.
If the goal is to improve our knowledge, why not just ask the model directly instead of reading someone else's post?
Could it be that, when we read, what we are really consuming is someone else's interests and preferences, or what they want us to see, and that the content itself has little value—that we are looking at the person rather than the words?
From the perspective of information theory, what does this mean? How would Shannon see it?
In the past, we primarily transmitted information through text. But with the development of the modern internet, much content can be replaced with abbreviations—like "NBA"—because human knowledge bases and the internet can automatically decode them.
So, what happens when we
have large language models?
If we can generate a full article with a single prompt, is the real information contained only in that prompt?
Is what truly needs to be transmitted simply the prompt and the model settings behind it?
After all, a 2000-word article might just be an expansion of a 30-word prompt.
当社交媒体上的帖子都由 AI 生成时,我们为什么还要花时间阅读?
别人几秒钟就能生成一篇帖子,我们却要花几分钟读完。
如果目的是增长知识,为什么不直接问模型,而要阅读别人发的帖子?
会不会我们在阅读时,真正消费的是别人的兴趣、偏好,或者他们想让我们看到的东西,而内容本身价值不大——我们看的其实是人,而不是文字?
从信息论的角度看,这意味着什么?香农会怎么看?
过去,我们主要通过文字传递信息。但随着现代互联网的发展,许多内容可以用缩写代替,比如“NBA”,因为人类的知识库和互联网能够自动解码它们。
那么,当我们
拥有大语言模型时,会发生什么?
如果只用一条提示词就能生成一篇完整的文章,真正的信息是否仅包含在那条提示词里?
真正需要传递的,是否只是背后的提示词和模型设置?
毕竟,一篇 2000 词的文章,可能只是对一条 30 词提示词的展开。